Boyuan Sun (孙博远) is currently a 4th year Ph.D. candidate at Nankai University, supervised by Prof. Qibin Hou and Prof. Ming-Ming Cheng. He received his bachelor's degree from the School of Computer Science and Technology at Xidian University in 2021. And now he is taking the Master-Ph.D. combined program in Nankai University. His research interests include Computer Vision and Multimodal Large Language Model, particularly focusing on multi-modal visual perception, vison-language model, semi-supervised learning, etc.
Internship Experience
 Ubiquant
Working on foundation models for agentic science, focusing on AI for Science and building Science Agent systems.
 ByteDance
Working on streaming video understanding and omni models. Focusing on agentic RL and on-policy training for streaming video.
 Shanghai AI Laboratory
Working on Science Discovery Agent System, focusing on MLE agentic model design, Data analyze agent, and agentic model training.
 Tongyi Lab, Alibaba
Focused on video understanding techniques, especially on training-free token compression, omni model architecture, and fine-grained object understanding for large multimodal models.
Selected Publications
* Equal contribution. # Corresponding author.
Scaling the Horizon, Not the Parameters: Reaching Trillion-Parameter Performance with a 35B Agent
Technical Report
A long-horizon scientific agent that combines domain-specialist training and multi-teacher on-policy distillation to support extended research workflows.

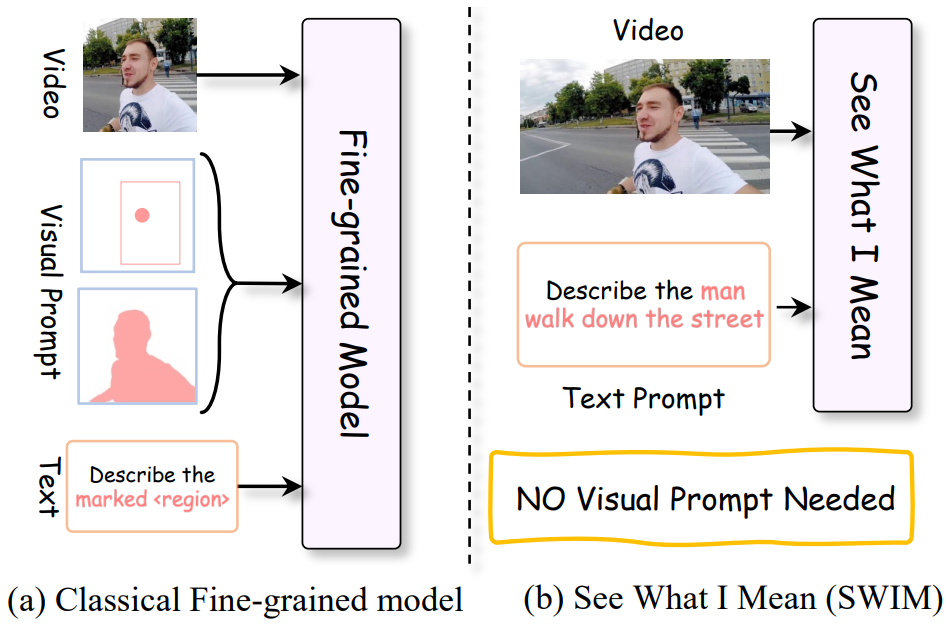
See What I Mean: Aligning Vision and Language Representations for Video Fine-grained Object Understanding
IEEE Computer Vision and Pattern Recognition 2026 (CVPR 2026)
Training-time mask supervision aligns natural-language references with visual objects for fine-grained video understanding without visual prompts at inference.
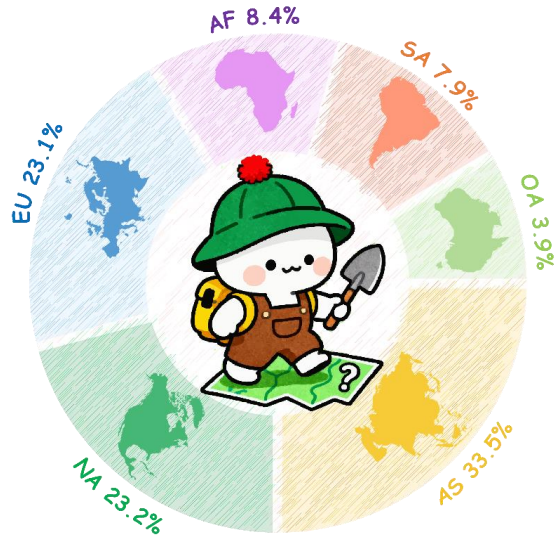
GeoAgent: Learning to Geolocate Everywhere with Reinforced Geographic Characteristics
IEEE Computer Vision and Pattern Recognition 2026 (CVPR 2026 Highlight)
A visual geolocation model trained with expert reasoning data and geographic similarity and consistency rewards to infer fine-grained locations.
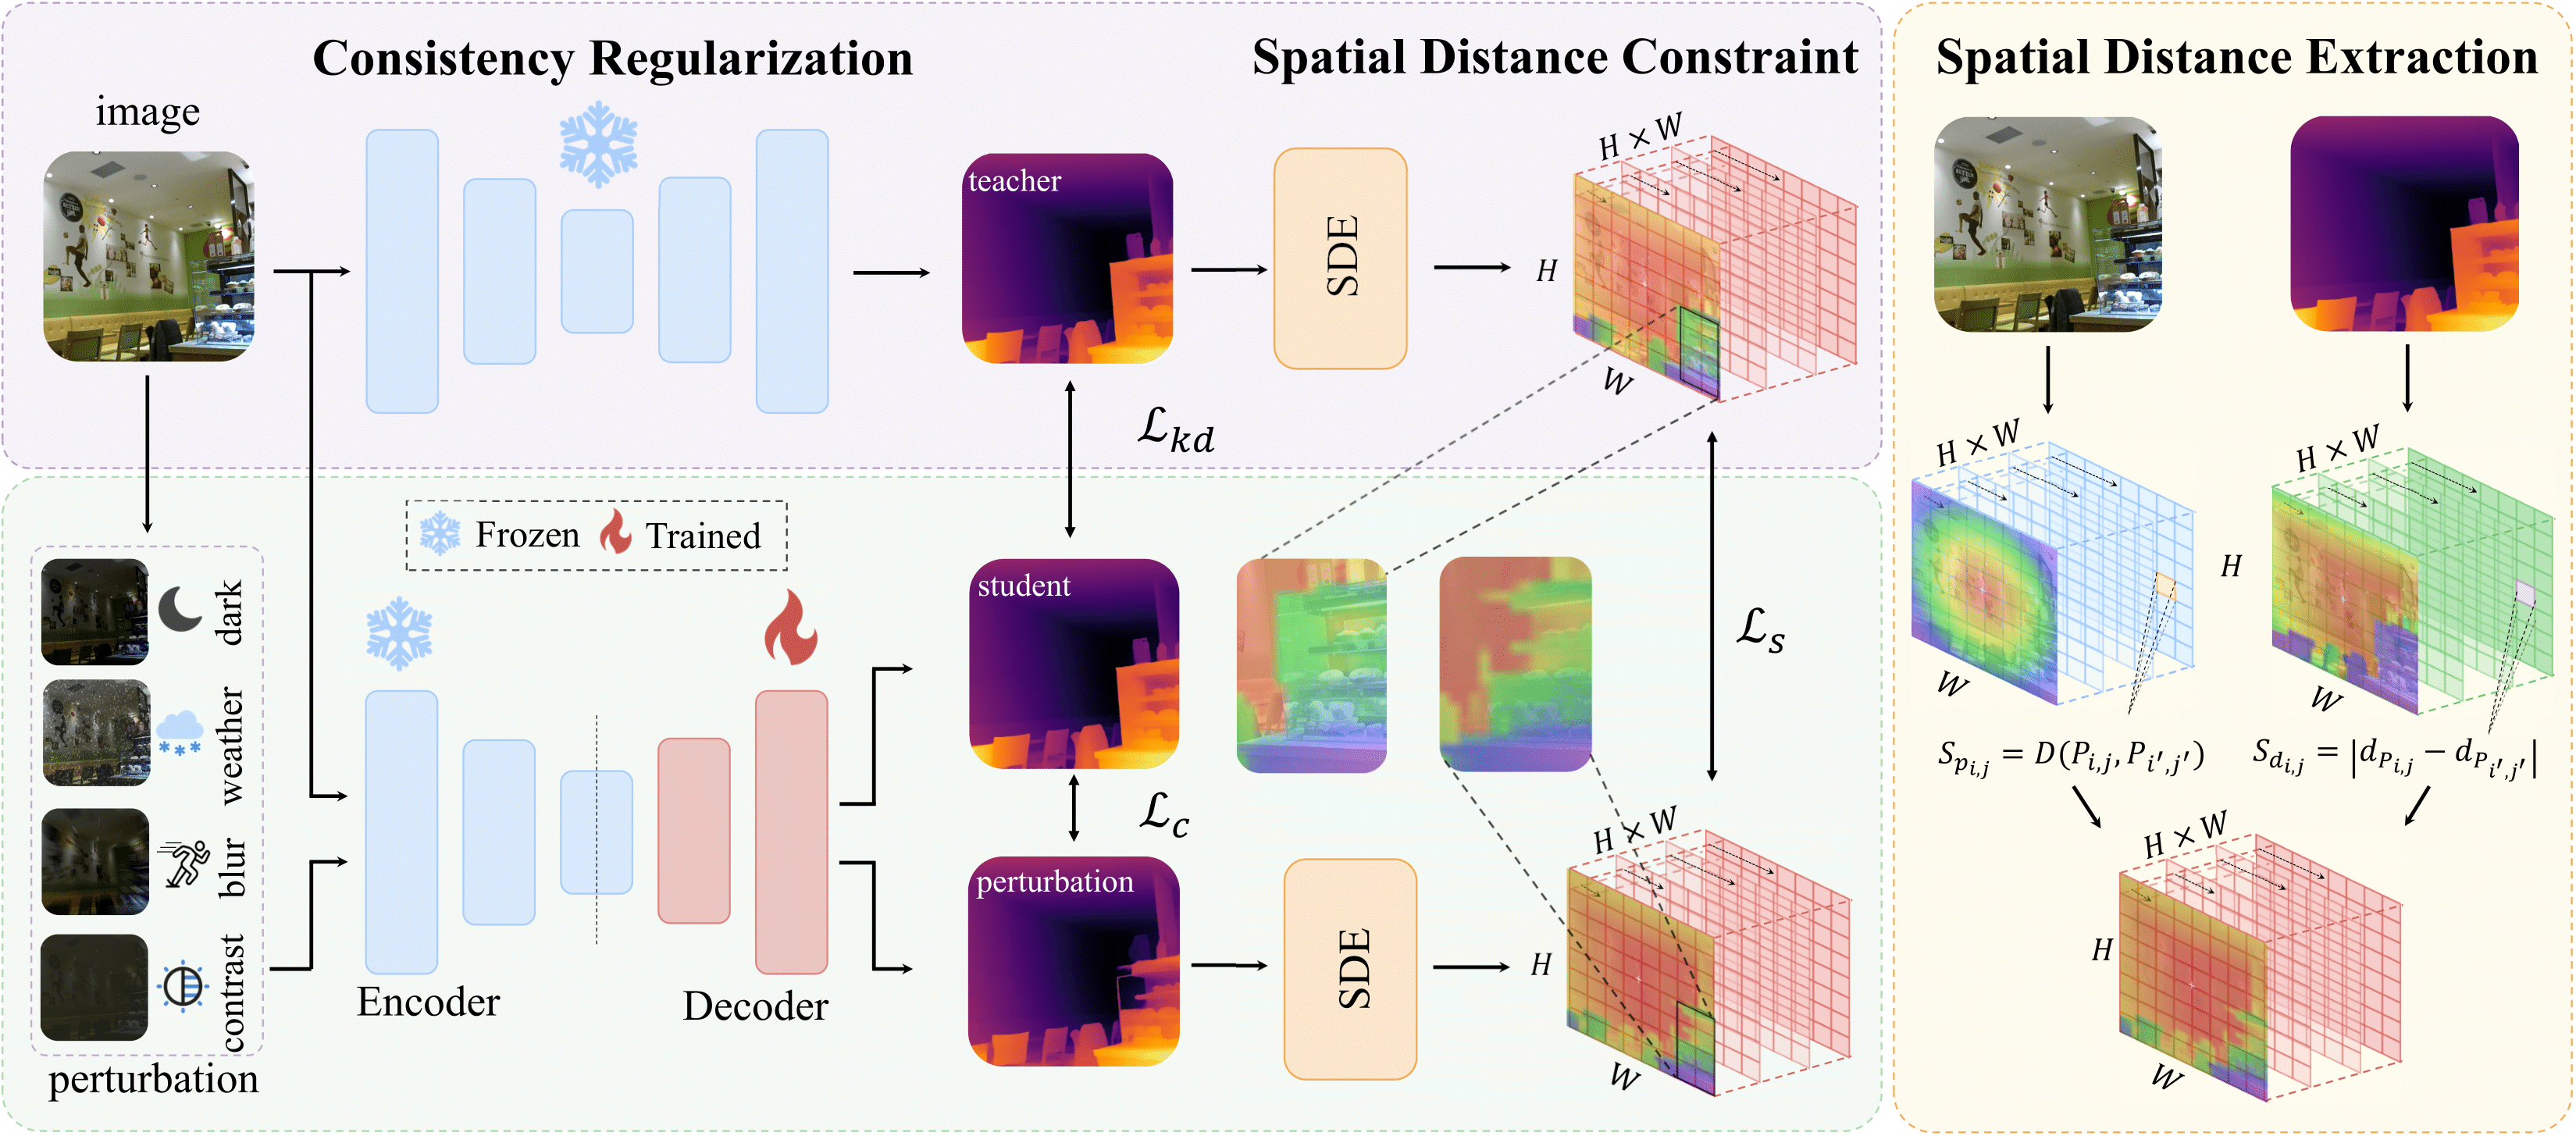
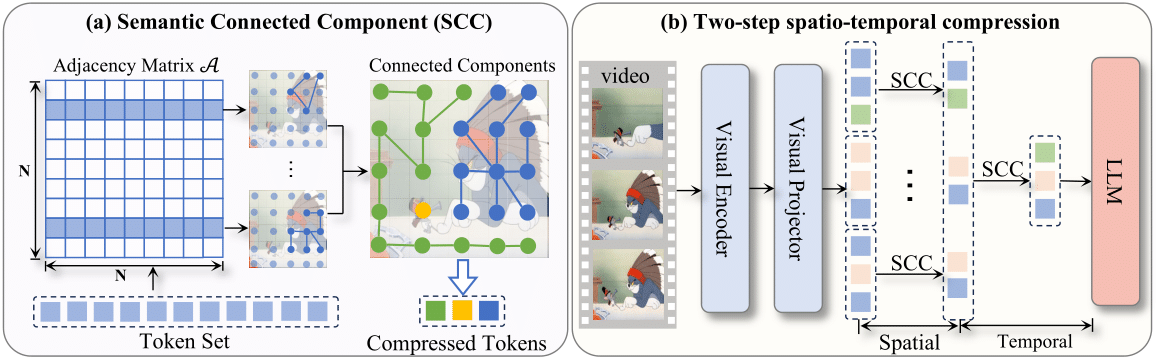
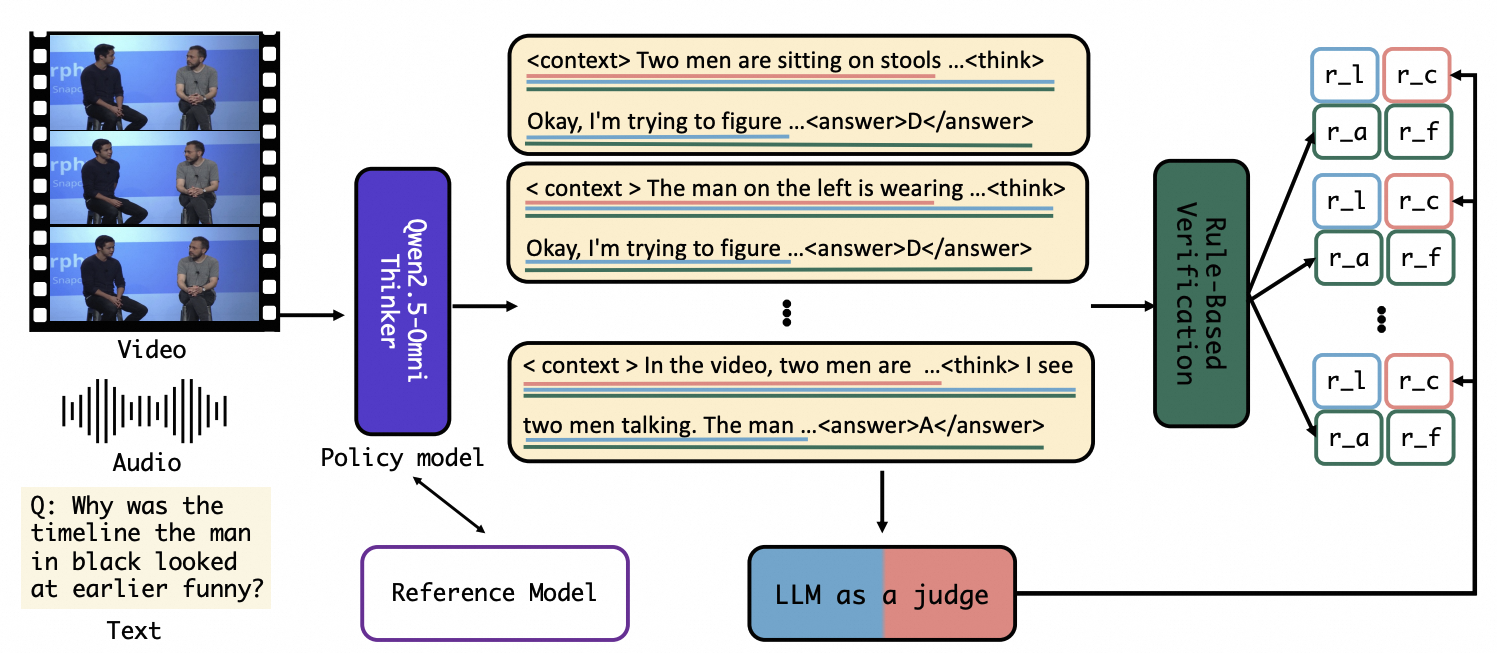
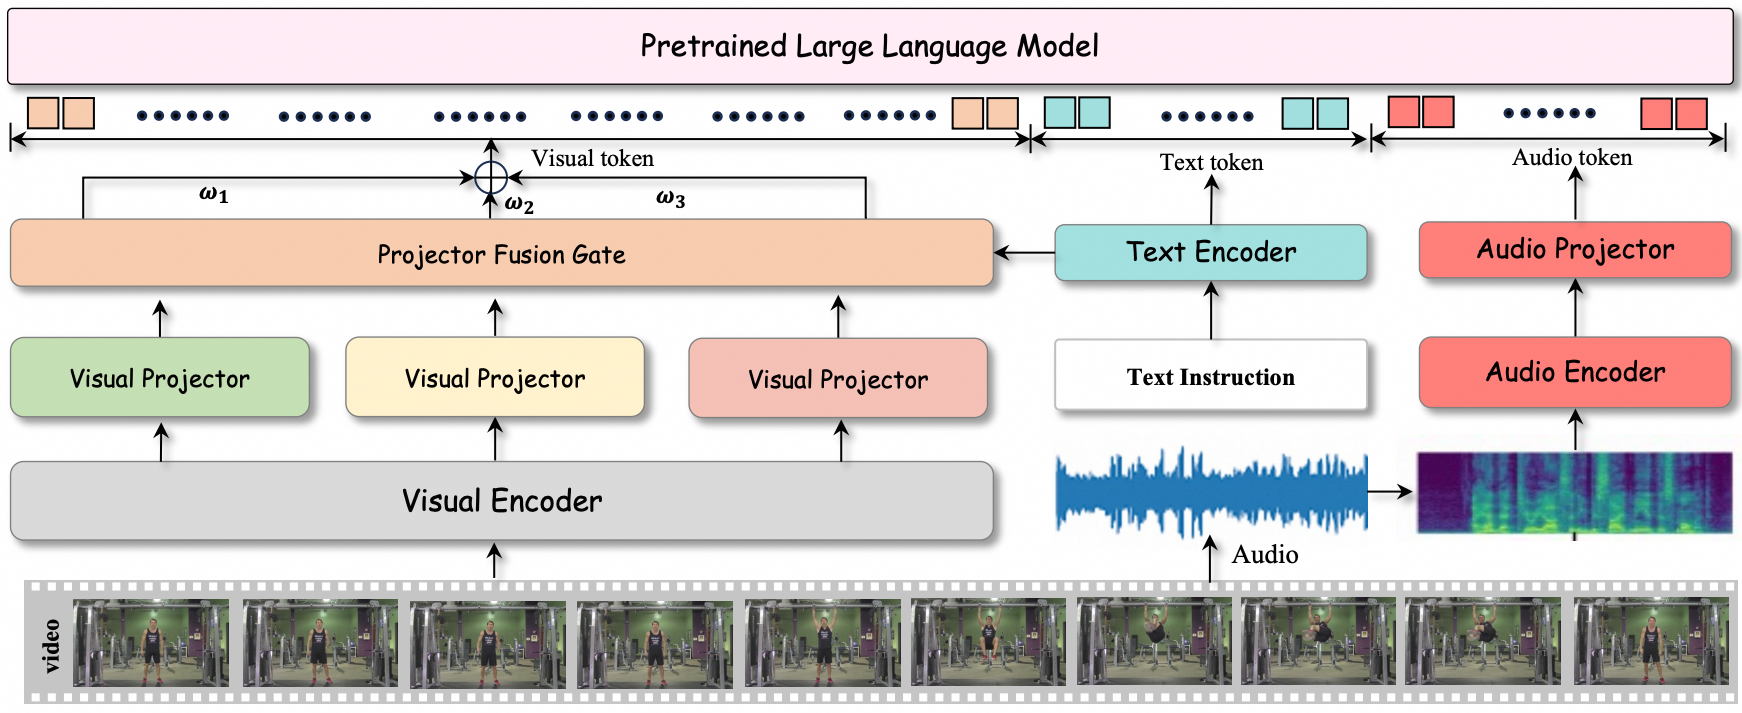

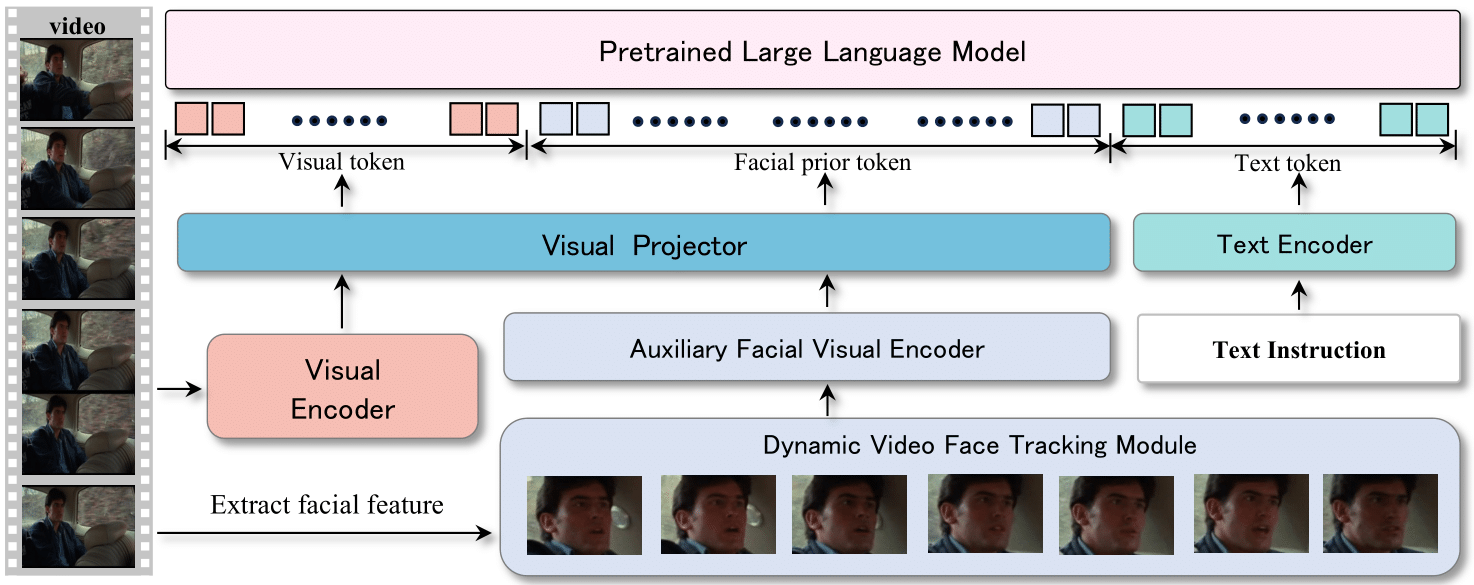
Facial Dynamics in Video: Instruction Tuning for Improved Facial Expression Perception and Contextual Awareness
Association for the Advancement of Artificial Intelligence 2026 (AAAI 2026)
A facial dynamics dataset and instruction-tuning framework support video-based expression understanding, with evaluation of event content and temporal order.
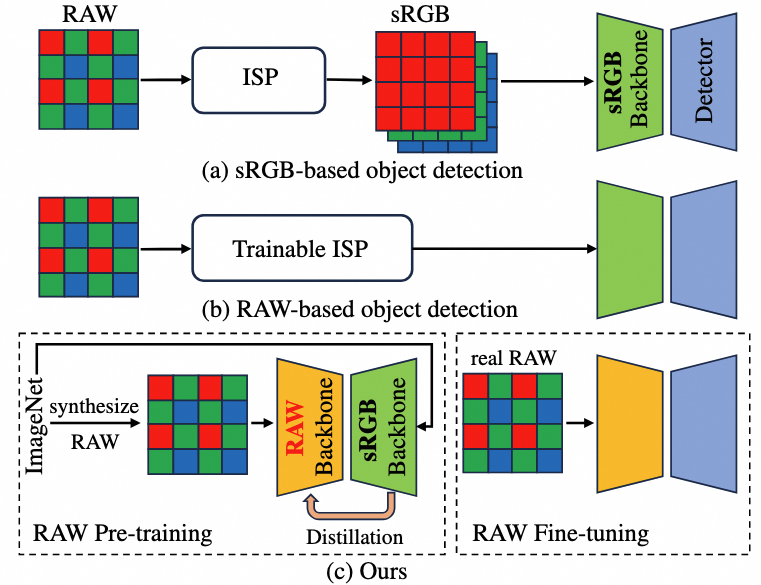
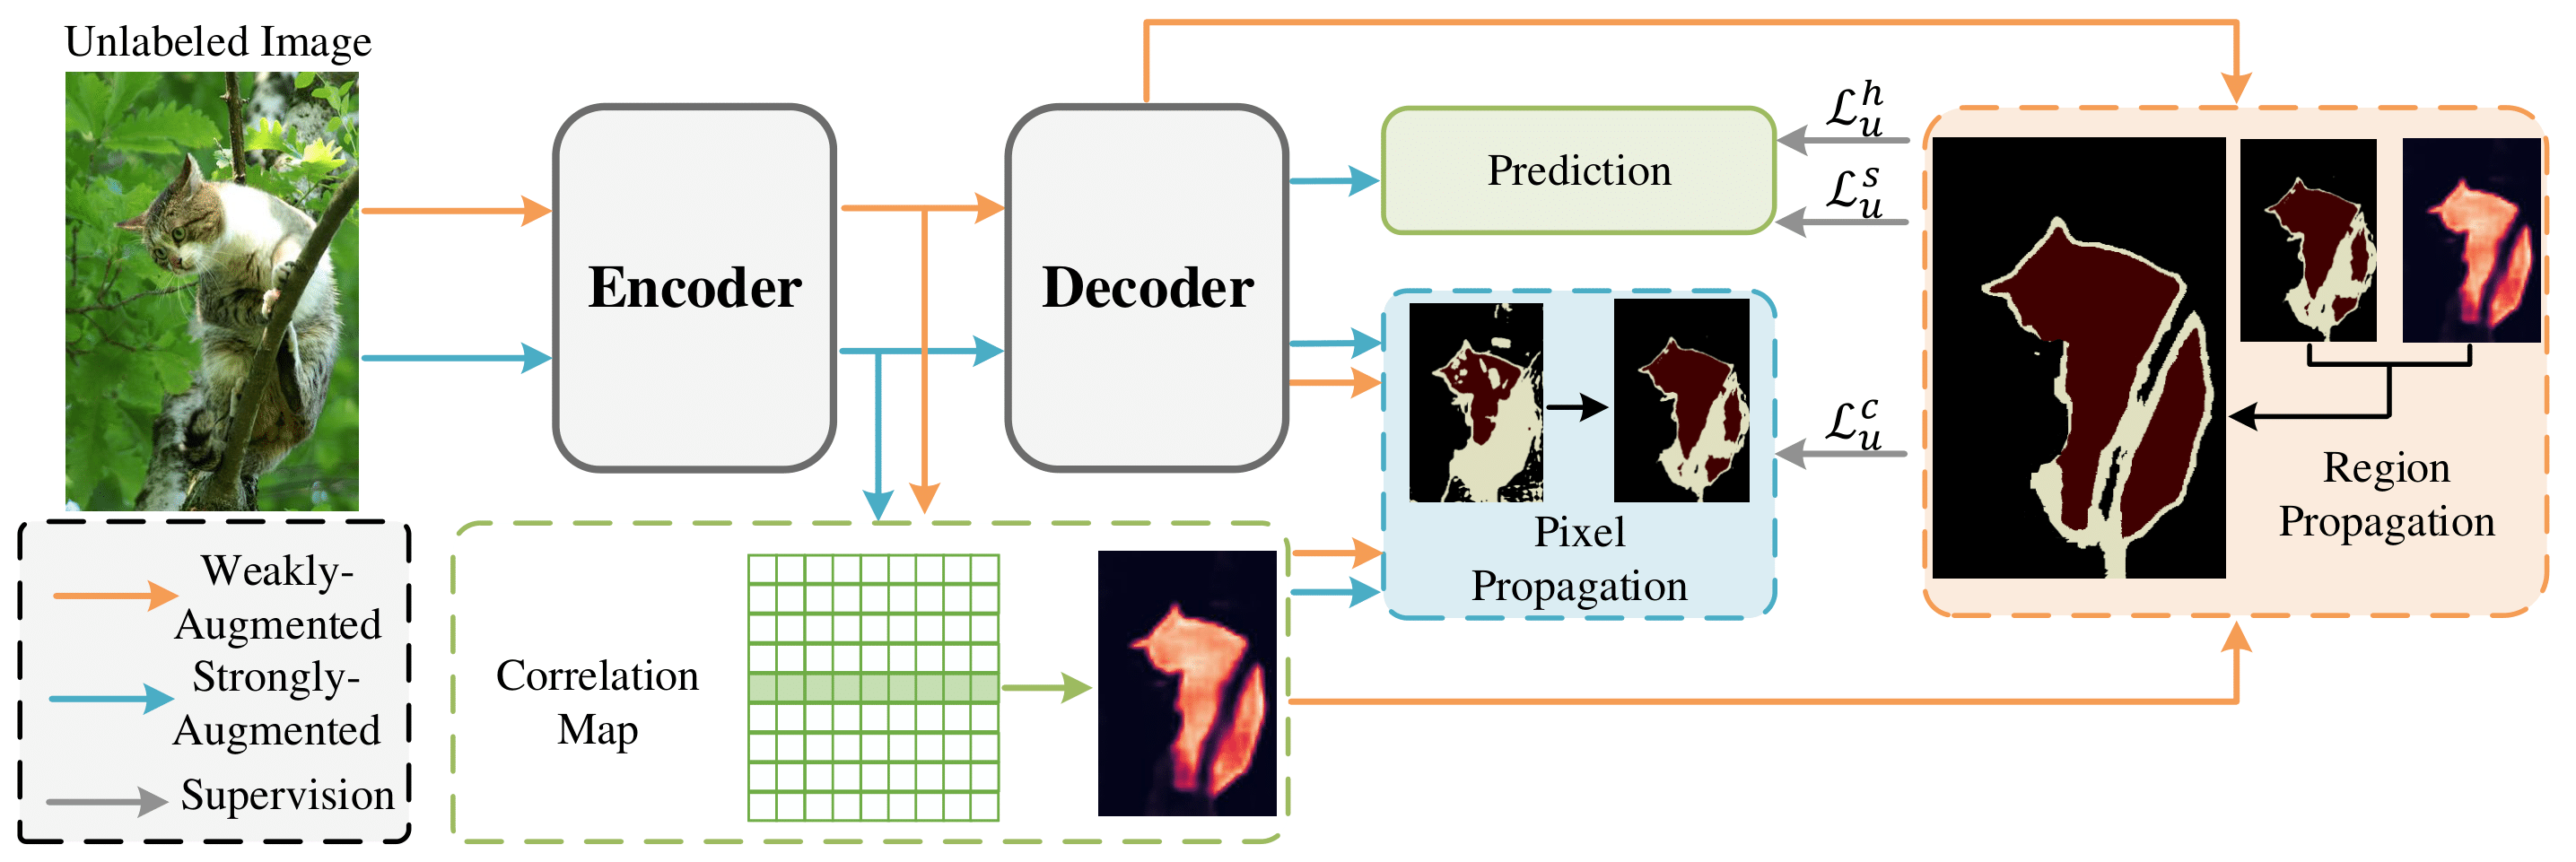
CorrMatch: Label Propagation via Correlation Matching for Semi-Supervised Semantic Segmentation
IEEE Computer Vision and Pattern Recognition 2024 (CVPR 2024)
Pixel and region label propagation through feature correlations makes better use of unlabeled images for semi-supervised semantic segmentation.